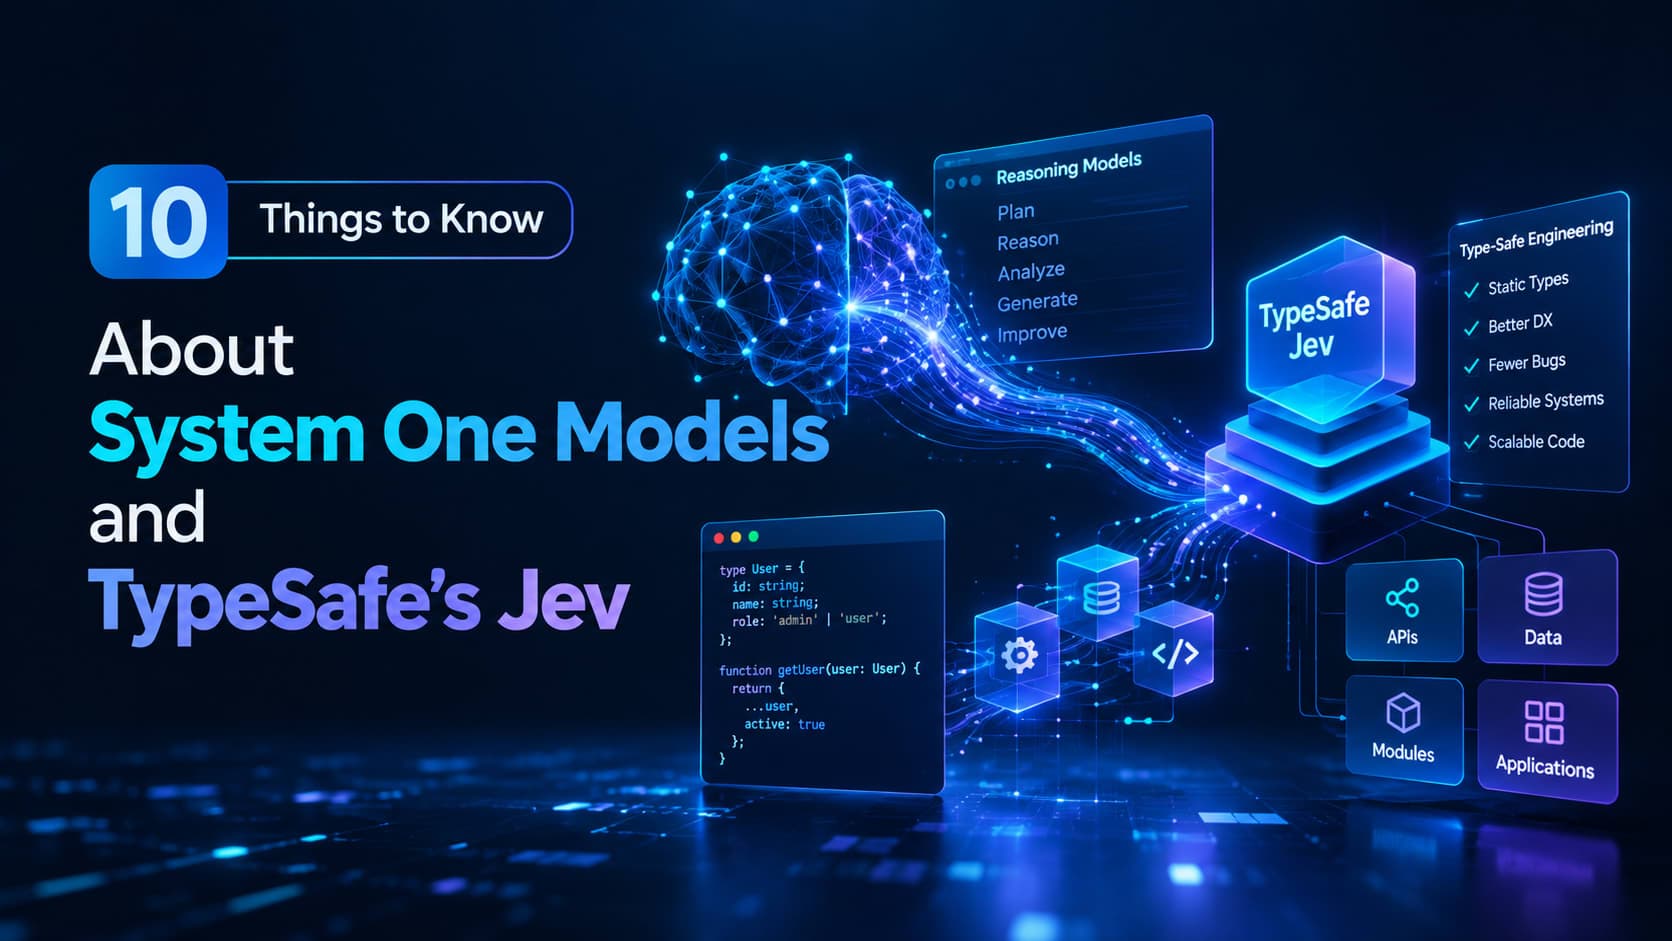
10 Important Things to Know About System One Models and TypeSafe’s Jev
Discover 10 important facts about TypeSafe’s Jev, System One Models, their performance, confidence signals, use cases, and developer considerations.
AI has become very good at generating text. But many software applications don't need another paragraph. They need a decision.
Should a support ticket go to billing? Should a transaction be reviewed? Which workflow should run next?
That's the problem TypeSafe is trying to address with System One Models.
Here are 10 things developers and technology decision-makers should know.
1. System One Models are built around decisions
Traditional LLMs generate language one token at a time. If an application needs to act on that response, developers may need to parse and validate the generated text.
TypeSafe's approach is different. A System One Model receives application state and a typed question, then returns a defined result.
A simplified example looks like this:
Support ticket
      ↓
Jev
      ↓
Choice: billing
Probability: 0.82
Confidence: 0.91
      ↓
Send to billing queue
The output isn't intended to be a conversational answer. It's information an application can use as part of its own logic.
TypeSafe describes Jev around three decision primitives:
Noul: a yes/no decision with a probability
Choice: one option from a defined set, with a distribution and confidence
Score: a rating with a distribution and confidence
The current TypeSafe evaluation documentation provides more detail on these primitives. TypeSafe evaluation documentation
2. Jev is TypeSafe's first public System One Model
Jev is the first public implementation of TypeSafe's System One approach.
Imagine a support platform receiving thousands of customer requests. One part of the workflow might ask:
Which team should handle this request?

- Billing
- Technical
- Sales
A developer can then use the resulting decision to determine what happens next.
This type of workflow is different from asking an LLM to write a natural-language explanation and then extracting the answer from it.
The application defines what a valid answer looks like before the model makes its decision.
3. Probability and confidence are separate signals
This is an important detail when evaluating Jev.
TypeSafe's documentation treats the probability distribution and confidence as separate pieces of information for its Choice and Score primitives. TypeSafe evaluation documentation
A simplified result could look like:
billing:    0.82
technical:  0.13
sales:      0.05

confidence: 0.91
The probabilities describe how the model distributes probability across the available outcomes.
Confidence is an additional signal describing how certain the model is about the decision.
Developers shouldn't assume that these numbers can be used interchangeably. If an application is going to use confidence thresholds such as "automate above 90%, send everything else to a human," those thresholds need to be tested against real application data.
TypeSafe says its RLCD training approach is intended to improve the calibration of these decision signals. TypeSafe: Introducing System One Models and Jev
4. RLCD focuses on calibrated decisions
TypeSafe calls its training approach Reinforcement Learning for Calibrated Decisions, or RLCD.
The basic idea is that a model making decisions needs useful uncertainty estimates, not just an answer.
For example:
High confidence
      ↓
Automate

Low confidence
      ↓
Human review
That can be valuable in production because uncertainty becomes part of the workflow.
TypeSafe contrasts RLCD with approaches such as RLHF and RLVR:
ApproachPrimary focus RLHFHuman-preferred responses RLVRProgrammatically verifiable results RLCDCalibrated decisions
The practical question for developers is whether those calibrated signals remain reliable on their own data. That's something a benchmark can suggest, but a production evaluation needs to establish.
5. TypeSafe reports significant speed and cost advantages
What TypeSafe reports
TypeSafe reports Jev response times of roughly 70 to 500 milliseconds and says it is approximately 40x to 200x faster than the frontier models used in its comparison for the types of queries it targets. TypeSafe: Introducing System One Models and Jev
Its public evaluation also compares models across example workflows involving customer service, invoice processing, security incidents, and agent-trace observability. The evaluation looks at factors including accuracy, cost, and time. TypeSafe workflow evaluations
How to interpret it
These figures are TypeSafe's reported measurements, not independent industry benchmarks.
The evaluation methodology and comparison setup matter. TypeSafe explains that its workflows were created by its own model-capabilities team and that the reference models use a TypeSafe wrapper for structured decisions. TypeSafe: Introducing System One Models and Jev
That doesn't make the results irrelevant. It means developers should treat them as vendor-reported evidence rather than a final verdict on Jev's performance.
The useful test is your own workload.
If a decision currently takes several seconds, costs too much at scale, or requires complicated output parsing, measure what happens when you replace that specific step with Jev.
6. Jev fits several automation tasks
Jev can potentially be used anywhere an application needs a defined AI-assisted decision.
Common examples include:
Classification: Determine what type of request or document you received.
Routing: Choose the right team, workflow, or agent.
Scoring: Assign a defined rating or level.
Filtering: Decide whether an item meets a condition.
Guardrails: Check whether an AI agent's proposed action should proceed.
Data processing: Apply decisions across large datasets.
Real-time applications: Make decisions where latency directly affects the user experience.
TypeSafe's published customer-service evaluation provides a useful example. Instead of treating customer support as one large language-generation task, the workflow breaks it into individual decisions around areas such as intent, urgency, frustration, fraud, refunds, and handoffs. TypeSafe customer service evaluation
That is a practical way to think about where a System One Model could fit inside an existing application.
7. Type-safe output does not guarantee a correct decision
There's one limitation developers shouldn't overlook.
TypeSafe says Jev cannot produce outputs outside its predefined schema and uses the term "zero hallucinations" to describe this property. TypeSafe: Introducing System One Models and Jev
That claim needs to be understood in context.
Suppose the only valid outputs are:
approve
review
reject
The model can be restricted to those three choices.
But it can still choose the wrong one.
If the correct answer is approve and Jev returns reject, the output is structurally valid but the decision is incorrect.
So there are two separate questions:
Is the output valid?
Is the decision correct?
Type safety helps with the first. It doesn't automatically solve the second.
8. Jev isn't a replacement for every LLM
Jev is designed for structured decisions, not unrestricted language generation.
A general-purpose LLM remains better suited to tasks such as:
Writing
Creative generation
Open-ended conversation
Detailed explanations
Arbitrary code generation
Broad reasoning tasks
In practice, the two approaches could work together.
A general-purpose model could handle a complex language task, while Jev handles smaller decisions inside the resulting workflow.
For example:
Customer request
       ↓
General-purpose LLM
       ↓
Extracted application state
       ↓
Jev
       ↓
Routing / scoring / approval decision
       ↓
Software action
That architecture lets each model handle the type of work it was designed for.
9. Developers should test one real workflow first
If you're evaluating Jev, start small.
Pick one decision that is:
High volume
Easy to measure
Already handled by an existing system
Important enough that an improvement would have business value
Customer-ticket classification is one example.
Build a representative test set and compare your current solution with Jev.
Measure:
Accuracy: How often is the decision correct?
Calibration: Do confidence values match actual reliability?
Latency: How quickly does the complete decision return?
Cost: What does one decision cost?
Failure cases: Where does the model make mistakes?
Human-review rate: How many cases need escalation?
Then test different thresholds.
For example, you might find that high-confidence decisions can be automated while uncertain cases go to a human reviewer.
That gives you evidence for deciding whether a production rollout makes sense.
10. The bigger story is the interface between AI and software
Jev's benchmark numbers are interesting, but the interface is arguably the bigger story.
For years, the common AI pattern has been:
Prompt → Model → Text
System One Models introduce another possibility:
Application state → Decision → Software action
That could change how developers use AI in parts of an application where generating prose isn't useful.
A fraud system may need a risk decision.
A support platform may need a routing decision.
An AI agent may need a go/no-go check before taking an action.
A large data pipeline may need to classify millions of records.
In these situations, the output can be much simpler than a paragraph.
The real test for Jev is whether its reported advantages hold across independent workloads and production applications.
For now, start with one real business decision and see how Jev performs against what you're already using.
Frequently Asked Questions
What is a System One Model?
A System One Model is TypeSafe's term for an AI model designed to make fast, structured decisions that software can consume directly. Jev is TypeSafe's first public System One Model. TypeSafe: Introducing System One Models and Jev
What is Jev?
Jev is TypeSafe's first System One Model. It is designed for typed decisions and provides outputs including probabilities and, for certain decision types, confidence information. TypeSafe website
What is RLCD?
RLCD stands for Reinforcement Learning for Calibrated Decisions. TypeSafe describes it as its approach for training models around calibrated decision-making. TypeSafe: Introducing System One Models and Jev
Are Jev's probability and confidence values the same?
No. TypeSafe's evaluation documentation treats probability distributions and confidence as separate outputs for decision types such as Choice and Score. TypeSafe evaluation documentation
Can Jev make incorrect decisions?
Yes. A model can return a valid value from the required schema and still select the wrong answer.
Does TypeSafe claim Jev has zero hallucinations?
Yes. TypeSafe uses the term "zero hallucinations" in describing Jev's constrained output behavior. That claim refers to the model's inability to generate outputs outside its predefined schema. It should not be interpreted as a guarantee that every decision is correct. TypeSafe: Introducing System One Models and Jev
Does Jev replace general-purpose LLMs?
No. Jev is designed for structured decisions, while general-purpose LLMs remain useful for language generation, conversation, coding, and open-ended reasoning.
How should developers evaluate Jev?
Start with one measurable workflow and compare Jev with the existing solution on accuracy, calibration, latency, cost, and failure rates.
You Might Also Like
Website vs Web Application: What Does Your Business Actually Need?